RA Store, UAE, 2026
RA Store Avatar Kiosk
A live avatar that greets mall visitors and understands how people in the Gulf actually speak.
At a glance
- fewer errors than ElevenLabs
- 33%
- voice score in blind tests
- 14/14
- cloud calls, fully offline
- 0
- Role
- Speech pipeline, model evaluation, avatar build
- Stack
- Local speech recognition, Emirati text-to-speech, Unreal Engine 5 MetaHuman
Result
The local model beat ElevenLabs Scribe on three of five test sets and tied the other two, with no losses. In simulated lobby noise it made 33% fewer errors (0.627 vs 0.936 word error rate). In blind listening, the chosen voice scored 14 out of 14 against ElevenLabs' 7. Everything runs on the kiosk itself, with no per-request API cost.
The problem
A mall lobby is the worst place to listen. Visitors switch between Gulf, Levantine, Egyptian, and Sudanese Arabic and English, often mid-sentence, over echo and crowd noise. Cloud speech services mishear them, transliterate English words into Arabic script, and add a network round-trip to every answer.
What I built
- An evaluation harness that measures what breaks a kiosk, not just word error rate: code-switching, English kept in Latin script, and language-ID stability.
- Five test sets, including recordings from the kiosk itself and a simulated lobby with reverb, crowd babble, and far-field audio.
- A local speech model tuned for these dialects, compared against ElevenLabs Scribe with significance testing on every set.
- A natural Emirati voice, chosen by blind listening tests after every automatic metric picked the wrong system.
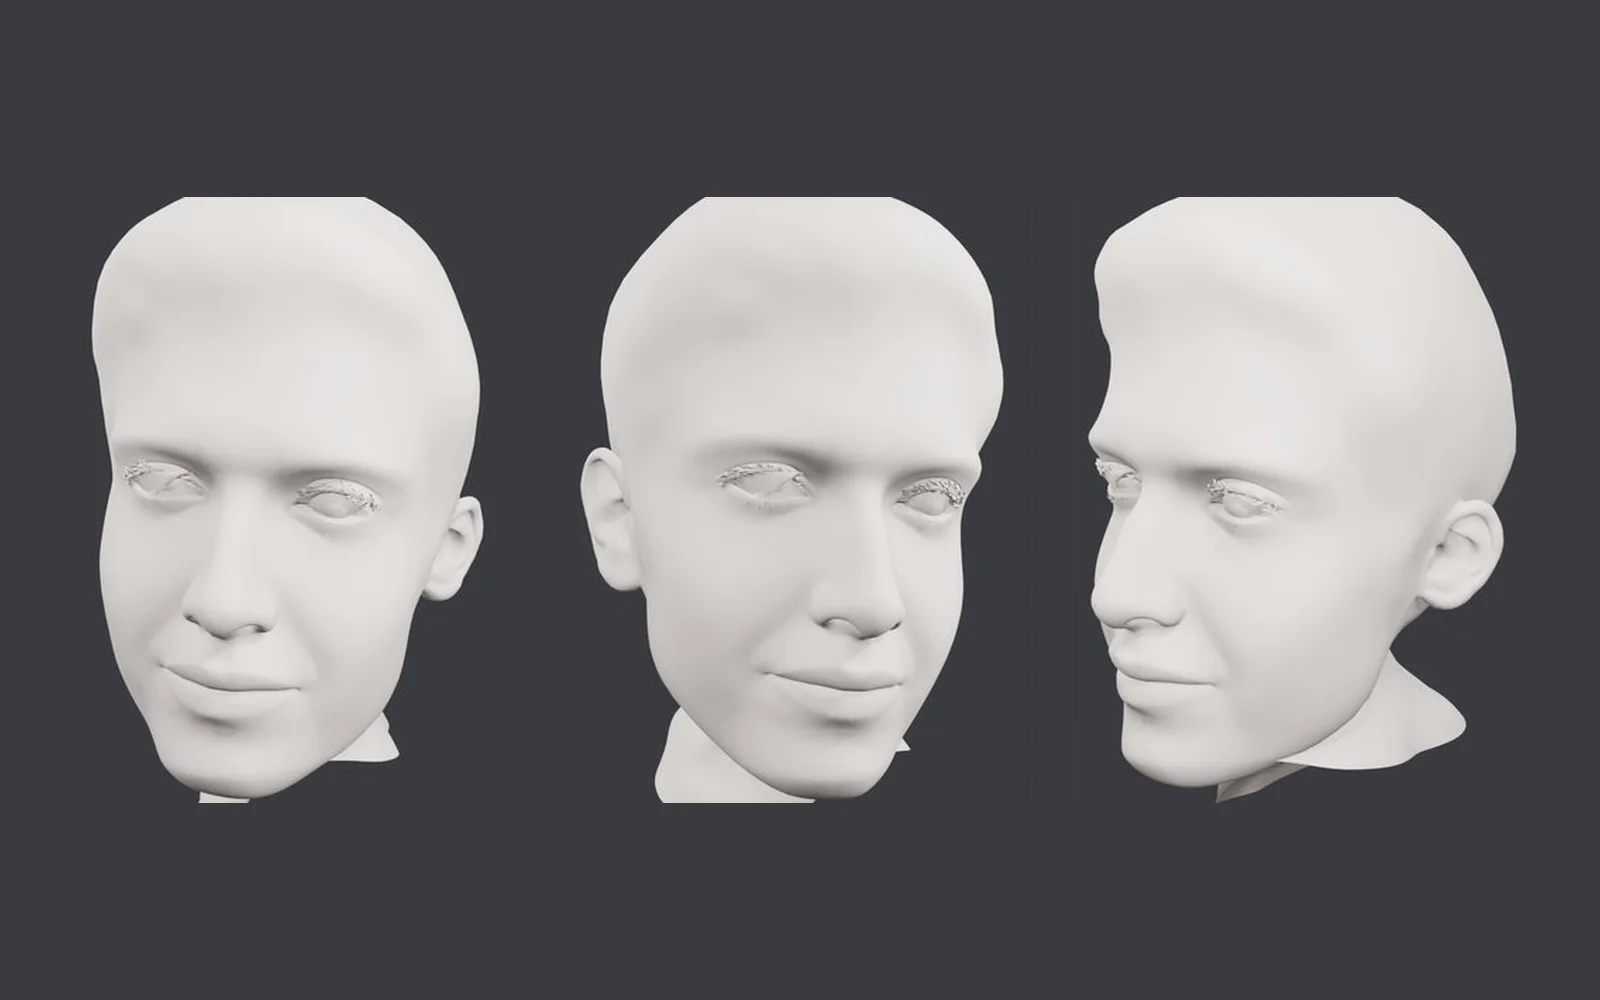
- A MetaHuman avatar built from a single photo: 874-bone facial rig, ARKit blendshape mapping, and LiveLink for real-time animation.
Stack
- Local speech recognition
- Emirati text-to-speech
- Unreal Engine 5 MetaHuman
- LiveLink
- Python evaluation harness
Want something like this for your team?
Get in touch